Ceiba Analytics - DocWeave
Intelligent Document Data Extraction and Parsing
Project Case Study
Advanced OCR system that automatically extracts structured data from PDF documents and converts it into CSV format. The system uses state-of-the-art text recognition and table detection algorithms to accurately parse complex documents, making data extraction fast and efficient for business intelligence and analytics.

- Department
- Industry Projects
- Status
- Alpha
- Tech Stack
- Python, Tesseract, PyPDF2
Item 1 of 2
Resources
More from the portfolio
 Industry Projects
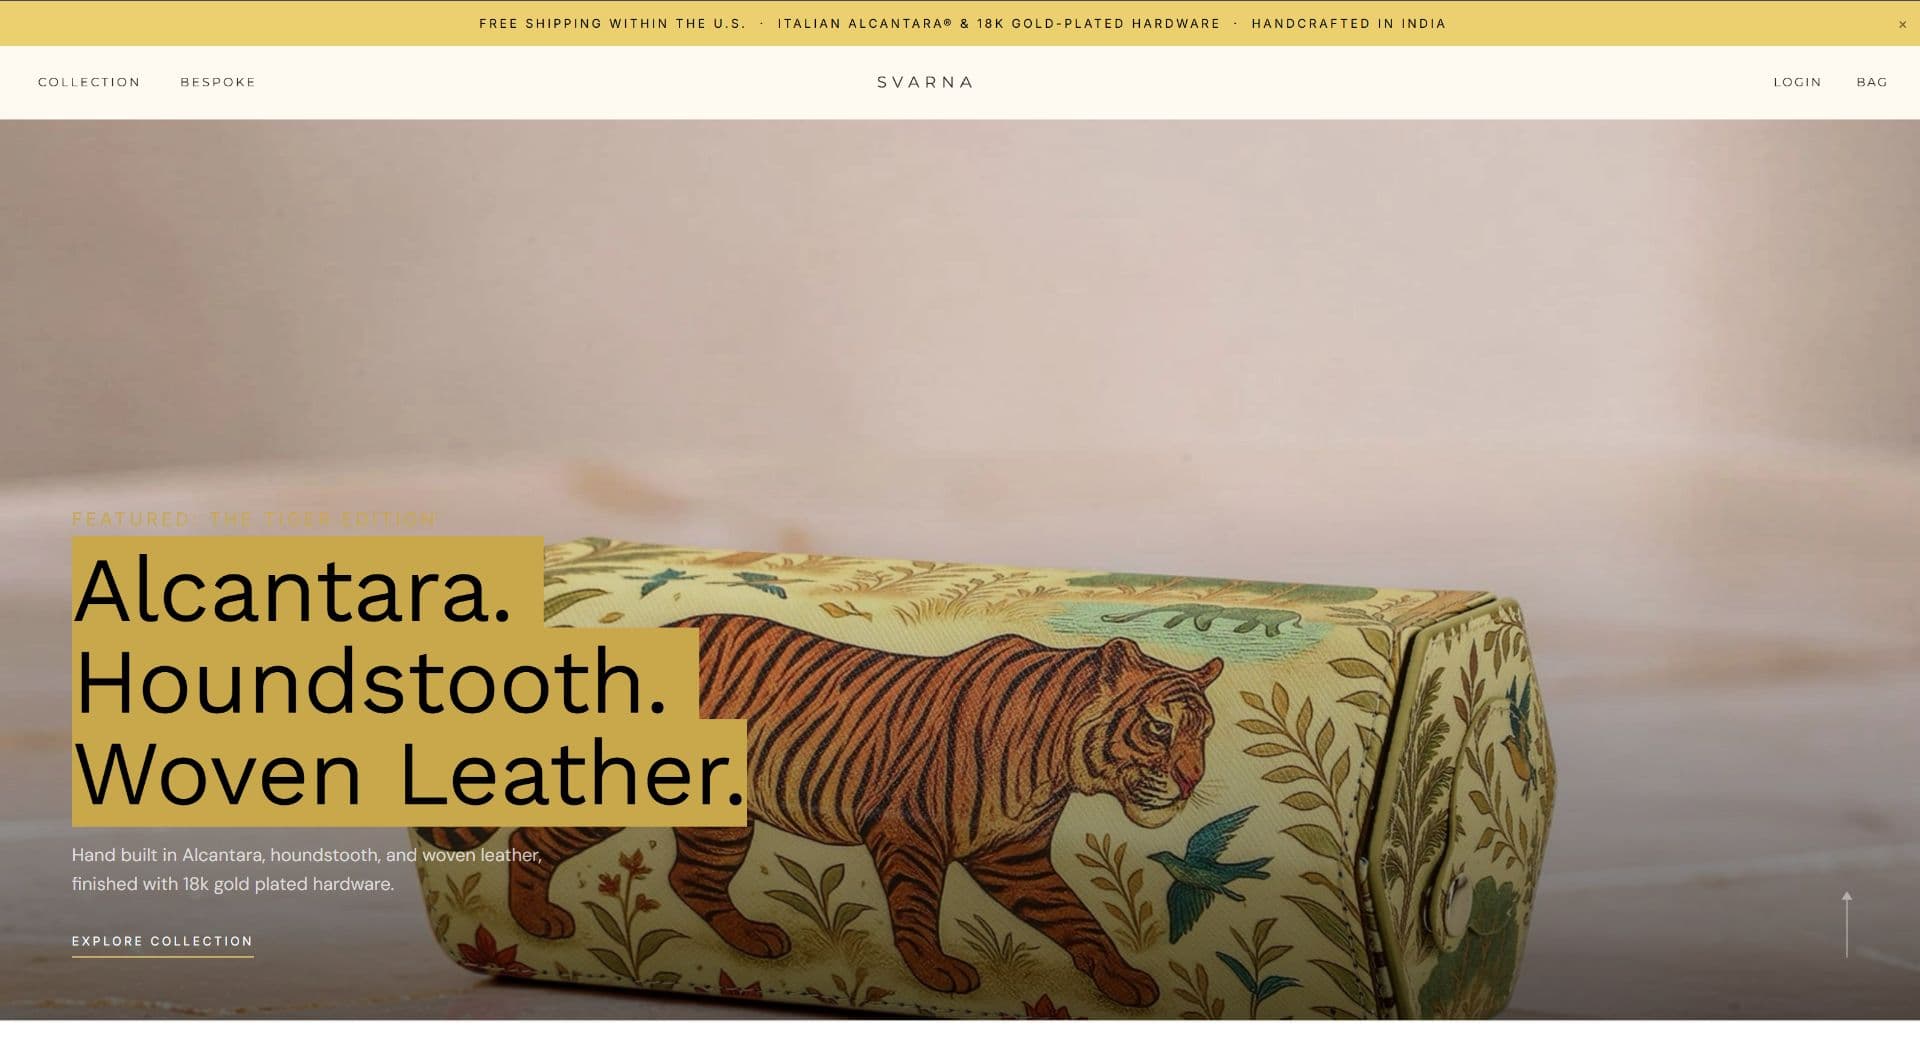
Svarna Heritage
SVARNA Heritage is an ultra-luxury Direct-to-Consumer (D2C) e-commerce platform designed for handcrafted watch rolls and bespoke leather accessories. It combines WebGL 3D product visualization, real-time color configuration, headless CMS management, and an enterprise admin analytics suite to deliver sub-second page performance.
View Project — Svarna Heritage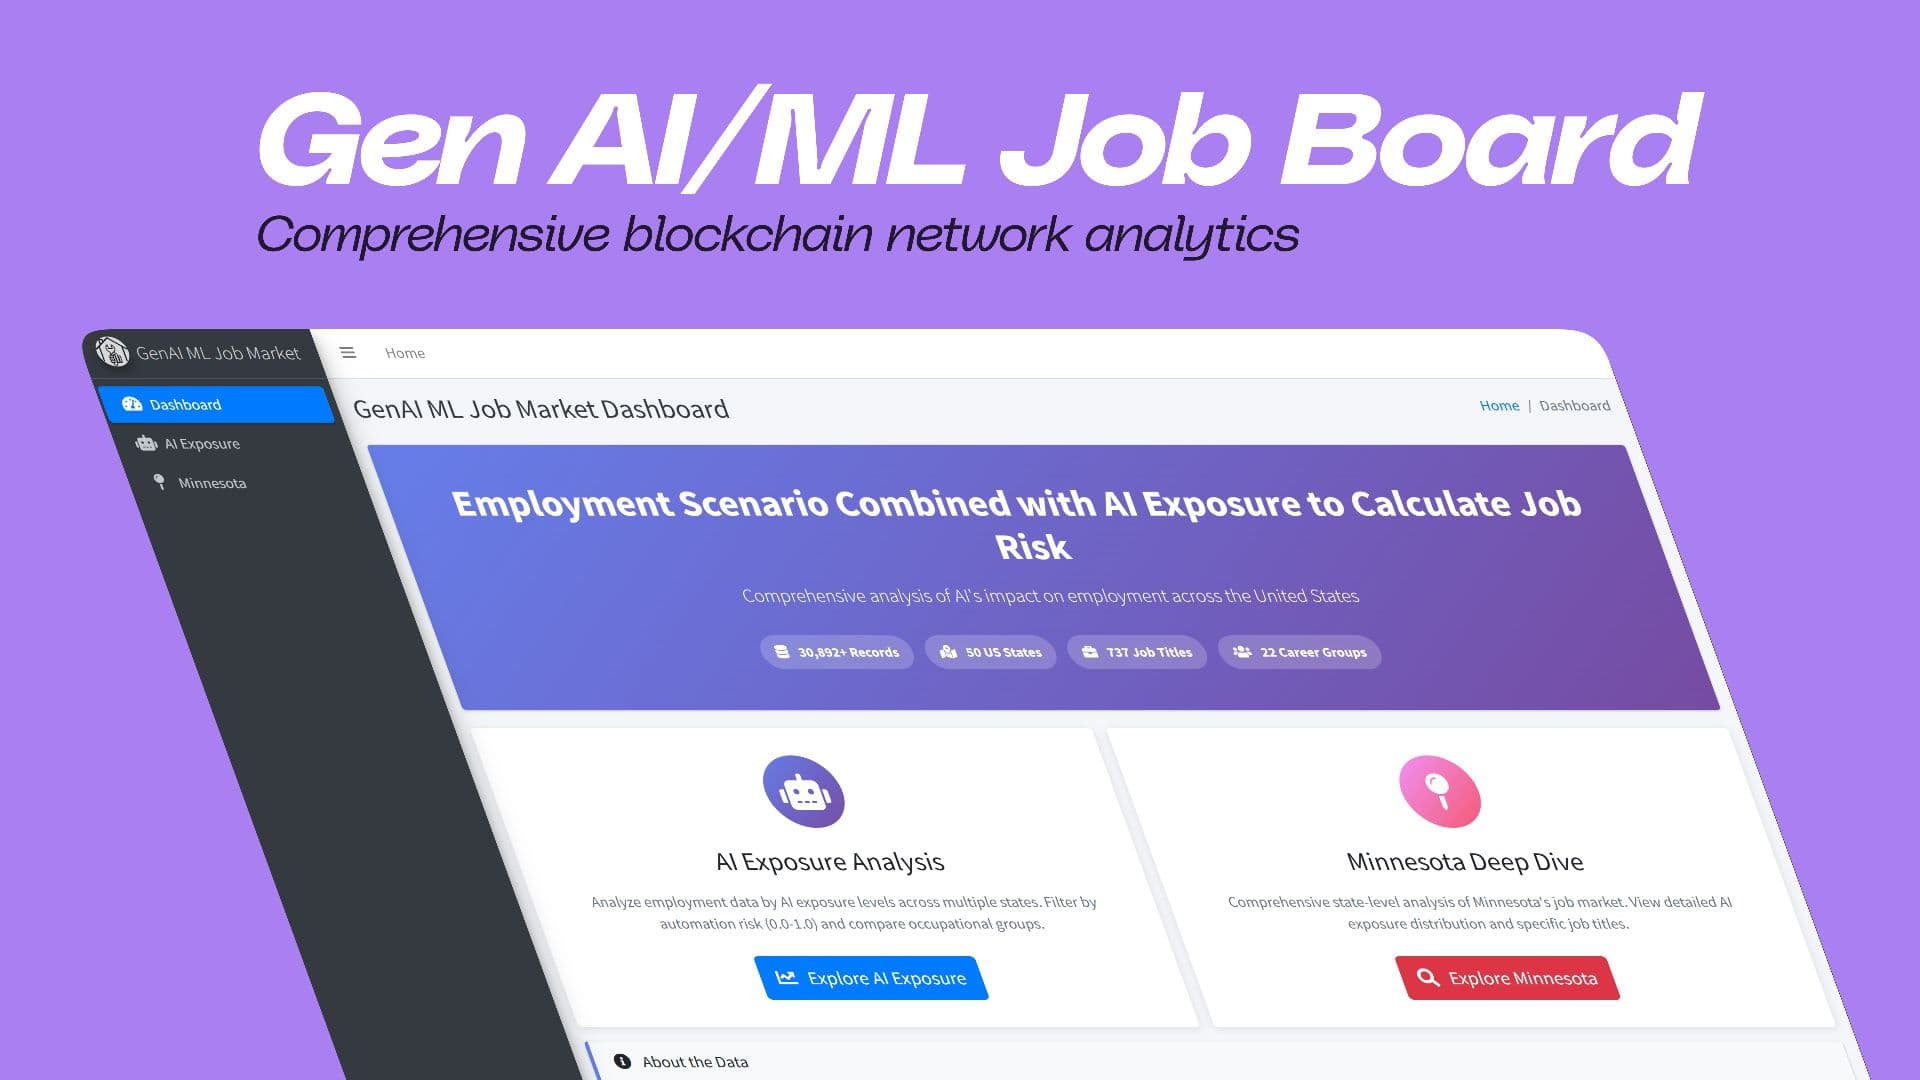 Industry Projects
GenAI ML Job Market
Employment Scenario Combined with AI Exposure to Calculate Job Risk
View Project — GenAI ML Job Market Industry Projects
QuantumFai - Startup Ai
Quantify your startup. Tokenize your value. Match with the right investors.
View Project — QuantumFai - Startup Ai
FaQ
Got questions? We've got answers!
Explore common inquiries about the work in our portfolio, how it is built, and how to use it.
- Every project is built inside the AI Research Centre at Woxsen University by our research staff, engineers and student researchers, usually alongside a department lab and often with an industry or academic partner.
- Several are available to pilot or license. Projects marked Production or Beta are the ones furthest along — get in touch through the contact form and we will put you with the team that built it.
- Alpha is an internal prototype under active research. Beta is running with real users outside the lab. Production is deployed and supported. Coming Soon is announced but not yet open.
- Yes. We take on sponsored research, joint development and student-led work across all of our departments. Tell us the problem you want solved and we will scope it with the relevant lab.
- It varies by project. Where we can publish, the repository, documentation and any accompanying papers are linked in the project's resources section. Everything else is available under agreement.
- New work is announced through our newsletter and the insights feed, and every project that ships gets a page here.
Still have more questions? Find answers in our help center.